Private GPU infrastructure
Private AI infrastructure that keeps sensitive work under your control.
We design and operate private AI infrastructure for training, inference, evaluation, voice, vision and enterprise knowledge workloads, from GPU sizing to the application layer above it.
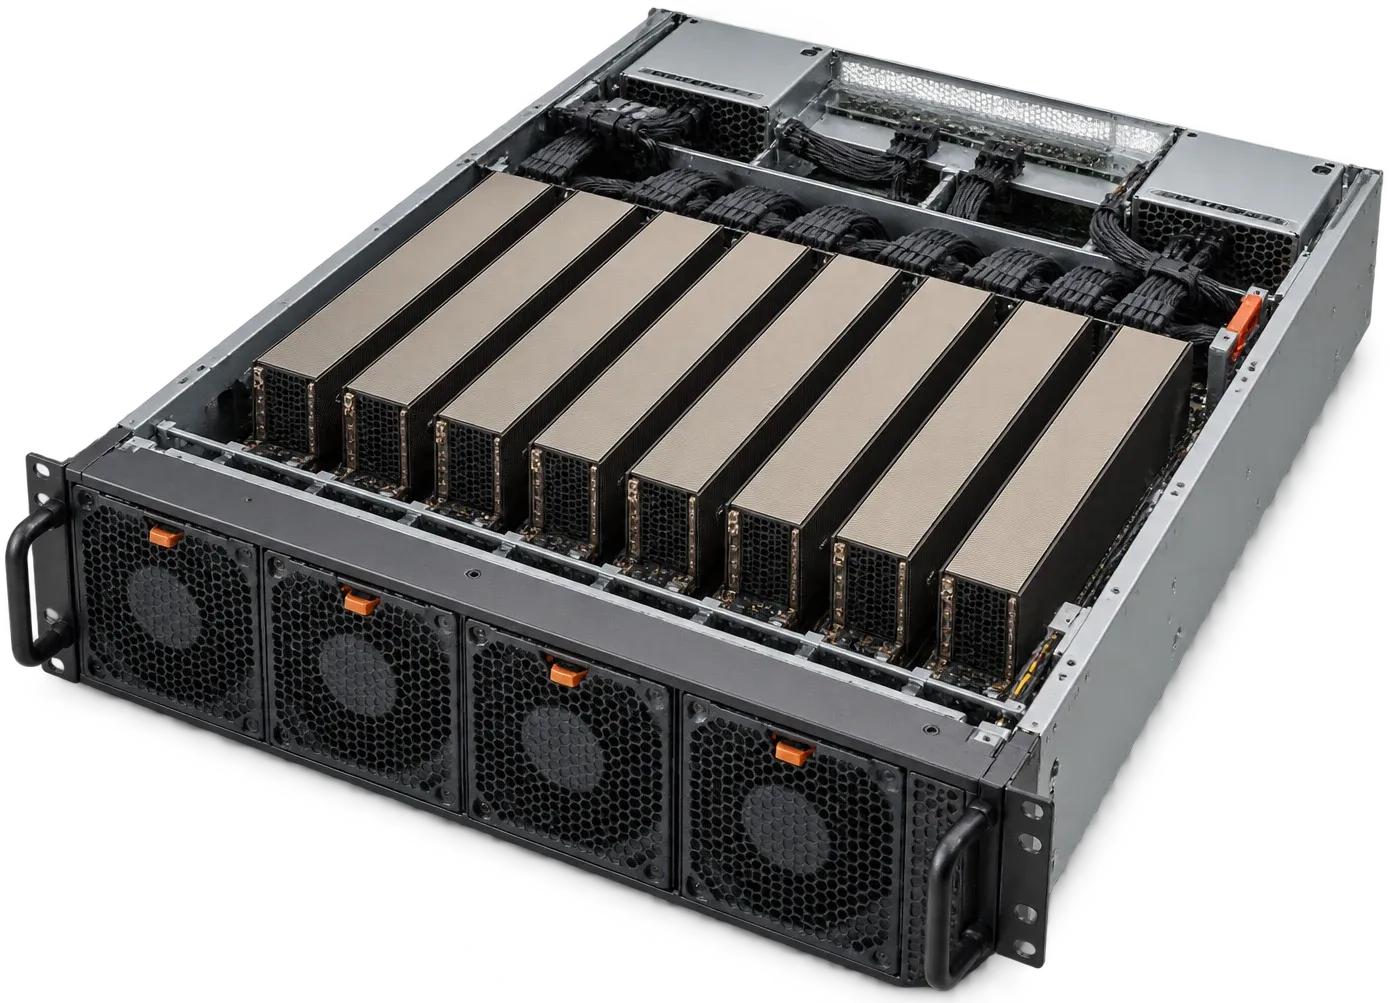
ORENCloud private GPU infrastructure services help organisations in Malaysia and the region run AI on their own premises or private cloud, for training, inference, evaluation, voice, vision and enterprise knowledge workloads. Work covers NVIDIA H200 and other GPU sizing, private model serving and on-premise, edge or air-gapped deployment. Contact us to size your workload.
Related: glossary, FAQ, about ORENCloud and trust.
Inside your data boundary
Your data
Documents, business systems, voice and vision.
Your AI environment
Local model serving with access and operating controls.
Your people
Answers and workflows delivered inside your data boundary.
Choose where your AI runs
Four common patterns. Pick one to see where the boundary sits and what crosses it.
We also design hybrid and controlled-egress set-ups that combine these, for example sensitive work on-premise and overflow in a private cloud.
On-premise
GPU servers in your own data centre or server room, with model serving, access control and monitoring set up by us. Updates come in through a controlled, approved path.
Makes sense when: Data cannot leave your boundary, or your team needs direct control over models, updates, logs and access.
Private cloud
Dedicated GPU capacity in a private cloud environment, reached from your offices over a private connection. You get the control without running the hardware yourself.
Makes sense when: Usage is large or steady, so dedicated capacity offers better control and economics than paying per call to a public AI service.
Edge
A compact GPU unit at the site runs vision, voice or language models next to where the data is created. Only alerts and summaries need to travel, and the site keeps working if the link drops.
Makes sense when: Latency or availability matters: the workload needs predictable response times or must continue with limited connectivity.
Air-gapped
A fully isolated environment with no network path to the outside. Models and updates arrive by approved offline transfer, and everything is logged inside the boundary.
Makes sense when: Regulation, contracts, security or internal policy require that sensitive data is processed entirely locally.
Hands-on, from sizing to operation
We work across hardware, Linux, model serving, networking, security boundaries, monitoring, and the applications that sit above the GPUs.
NVIDIA H200 and GPU systems
Workload sizing, server and cluster design, deployment, capacity planning and performance tuning.
Private model serving
Inference endpoints, model routing, access control, scaling, observability and cost tracking.
Local deployment patterns
Private cloud, on-premise, edge, hybrid, controlled-egress and fully air-gapped environments.
Private infrastructure is a business decision, not a badge
It makes sense when at least one of these is true. If none are, a managed service is usually simpler.
Data cannot leave your boundary
Regulation, contracts, security or internal policy require local processing.
Latency or availability matters
The workload needs predictable response times, or must keep running with limited external connectivity.
Usage is large or steady
Dedicated capacity may give better control and economics than paying a public AI service per call.
You need local ownership
Your team needs direct control over models, updates, logs, access and operating schedules.
What do you do for private AI infrastructure?
We design and operate it: workload sizing, server and cluster design, deployment, capacity planning and performance tuning, plus private model serving with access control, scaling, observability and cost tracking.
Which deployment patterns are available?
Private cloud, on-premise, edge, hybrid, controlled-egress and fully air-gapped environments.
When does private infrastructure make sense?
When data cannot leave your boundary, latency or availability matters, usage is large or stable, or you need local ownership of models, updates, logs and access.
Is this GPU rental?
No. This page describes design, deployment and operation of private infrastructure for you, not a self-service GPU rental offer.
Can I run ORENCloud AI products on it?
Yes. Local models can power iKB and Cosine inside your own data boundary.
How do we start?
Discuss your project with the workload, model and number of users in mind, or start with AI consulting to build the business case.
Start with a business problem
Tell us about the workload and the data rules it must follow. We will help you choose a practical deployment and size it.